Pages

Showing posts with label nlp. Show all posts

Chatterbots and Natural Language Processing: A real example with Brazilian Correios Bot TweetComendas

Tuesday, September 14, 2010

Hi all,

In a previous post at this blog I've presented two web robots that I developed : Tweetcomendas and TransitoRE.  For Tweetcomendas, which is a Twitter bot for track mail orders from Brazilian post office Correios, I've developed a chat bot to interact with the users. Besides Twitter,  the user  also can track his orders by asking at real-time our Chat Client TweetComendas.

Recently, several approaches were proposed in the research domain of chatterbots. But first let's review the concepts of a chatterbot or chatbot.  Chatterbots are computer programs that seek to simulate a human in the conversation with other people. Its goal is to answer questions in a manner that people have the impression they are talking with a real person and not a computer program. This  tatement remembers me the Turing Test which is a test proposed by Alan Turing in his 1950 paper in order to evaluate the machine's ability to demonstrate intelligence by using conversation between humans and machines. It's quite interesting, I recommend the reading.

So after the dispatch of the questions in natural language, the program consults a knowledge database and then provides an answer which tries to mimic the human behavior.  Although, many chatterbots do appear to simulate the human input intelligently in their responses,  the bot that I developed tries to simulate an human assistant by scanning for keywords within the input and answers the closest as possible in natural language the statuses of the orders at Brazilian Correios.

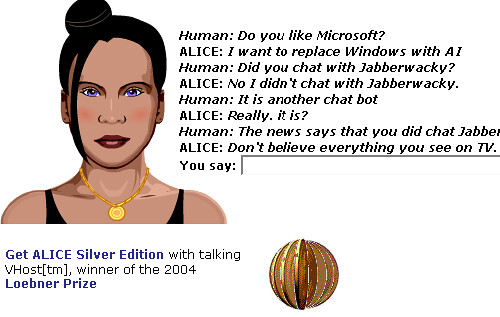
Recently, chatbot techniques have been used for several practical purposes such as online help, personalised services or information acquisition, by working as a conversational agent. One of the classical examples of Chatterbot is A.L.I.C.E, which uses a weak A.I.. In the example of A.L.I.C.E, it uses a programming language called AIML, which is specific to its function as a conversational agent and has been adopted by many developers, which created the called Alicebots.

A.L.I.C.E

The one that I've liked a lot and at some way inspired to develop my own bot was the Aadvark ChatterBot. Aadvark, recently bought by Google, was  a startup focused on creating a social recommendation engine mashing-up some components of Yahoo! Answers and Instant Messaging.  Their service is to offer the user the possibility of asking a question to the bot, and based on its algorithms it will compute its own tag (keywords or you could give it a few) and then, it will find a right person to your question and it will forward it to him in order to  answer. The best part is that Aadvark works very well not only in their web page but also in another clients such as IM's, Iphone, etc.  So you have a question, just open the chat screen of the bot and ask a question and after some minutes you may get a useful answer in the same session (client). Try it for free and see its power!

Aadvark Chat Client


The Tweetcomendas ChatterBot is actually a Jabber Chat Clients which uses the XMPP protocol for receiving and pushing text messages. I've used as an example of another bots that I am planning to develop. Let's see a working example of how it works:

1- First, we have to add the chatter bot tweetcomendas@bot.im (it uses the IMIFIED IM's  bots infrastructure, so you can host your bot there for free.).

2 - After he comes online, you can send at anytime the tracking code of your package order from Correios in order to track it.

It uses regular expressions to match the tracking code.

3 - Wait while he looks at the Correios Tracking WebServices and receive the current status.

The current status in natural language for the user.

3 - Now, another useful feature of the Tweetcomendas ChatterBot is he can actually track for you automatically your order and any new updates he will come to you by giving the new status on your chat client if you're online or by sending you an e-mail (It only works with gmail by now.)

He will ask you politely if you want him to track your order for you.

A gentleman chatterBot :D

4 - Receive new updates of your order by e-mail or by your Jabber Client.

Updates on your e-mail even when you 're not online at the Google Talk


So, this is my first attempt to develop real useful chatter bots for helping users in order to track their post orders. There are many ideas in my mind that I want to create. I believe this kind of tool is the next generation of agents for interacting with people working as an assistant such as the Siri: a mobile assistant agent running on Iphones.  Take a look at the video and see the future of those kind of technologies.


I expect that you have enjoyed my simple bot, it still sometimes can be lazy but in almost of the time it works smoothly. Add to your Google Talk Contacts:  tweetcomendas@bot.im   This is a personal experiment project that I've developed with the help of Ricardo Caspirro (@ricardocaspirro) on intelligent agents and bots.  If you want more information  about it, take a look at its homepage. There is also other client working on Twitter!


That's all,

Cheers,

Marcel Caraciolo

Knowing the 'hidden' class re.Scanner in Python and how to use it: Building a simple Tweet Extractor

Wednesday, September 8, 2010

Hi all,

I've written a simple post at my personal blog (Yes, I have one, but it talks more about my daily life, personal projects and geek stuff) Mobideia about the use of a hidden class 'Scanner' from the module re, responsible for handling with regular expressions.

The practical example includes a simple Tweet Extractor for identify the URLs, (http://www.aimotion.blogspot.com),  usernames (@joao), hashtags (#django), Retweets (RT) and words.  It may be very useful for you who wants to play with Natural Language Processing (NLP) and text mining on Twitter.

In order to avoid the replication of all text here,  I've decided to place the links for accessing the post:

Portuguese Version
http://www.mobideia.com/2010/09/uso-da-classe-escondida-scanner-em.html

English Version (by Google Translate):


http://translate.google.com/translate?js=n&prev=_t&hl=en&ie=UTF-8&layout=2&eotf=1&sl=pt&tl=en&u=http%3A%2F%2Fwww.mobideia.com%2F2010%2F09%2Fuso-da-classe-escondida-scanner-em.html


I hope you enjoy!

Cheers,

Marcel Caraciolo

Working on Sentiment Analysis on Twitter with Portuguese Language

Tuesday, July 20, 2010

Hi all,

In this post I would like to write about my last studies that I was  focusing on. In recent years it is noticeable the increase in amount of information available on the Web. People have started to share in the Web their knowledge and opinions in blogs, social networks and other medium.

On top of that, it have appeared a new research field related to Natural Language Processing, called Opinion Mining also known as Sentiment Analysis. Sentiment Anaylsis aims to identify the sentiment or feeling in the users to something such as a product, company, place, person and others based on the content published in the web. In the view of the requester, it is possible to obtain a full report including a summary about what people are feeling about an item without the need of find and read all opinions and news related to it.
In machine learning area, sentiment analysis is a  text categorization problem which desires to detect favorable and unfavorable opinions related to a specific topic. Its main challenge is to identify how the sentiments are expressed in text and whether they point a positive opinion or a negative one.

There are many applications for the use of Sentiment Analysis, some as follows:
  • Sentiment Analysis in Company Stocks :  An important data for investors in order to identify the humor of the market to the companies stocks based on the opinion of analysts, therefore, identifying the trends in their prices.
  • Sentiment Analysis in Products: A company might be interested in the opinion of their customers about a certain product. For example,  Google (or another company) can use the sentiment mining to know what the people are speaking about the Android cellphone: Nexus One. This information can be used to improve their products or even identify new marketing strategies.
  • Sentiment Analysis on Places:  One person who will travel might want know the best places to visit or the best restaurant to eat. The opinion mining could help those people recommending good places during the planning of their travel.
  • Sentiment Analysis on elections: The voters could use the sentiment analysis to identify the  opinion of other voters about a specific candidate.
  • Analysis on games and movies:  It is possible to mine the sentiments about games and even movies. We will talk more about this in the future.
Another application for sentiment analysis is on status messages on social networks such as Twitter or Facebook. Twitter has gained a special attention recently where people used it  to express their opinion on certain topic.  Therefore, applying sentiment analysis tools  for Twitter that attempt to classify tweets into either positive, negative or neutral categories  automatically could be quite useful for companies and marketers. It is a widely public data source that couldn't be ignored.

Of course, there are several tools in this area, but more focused on classifying tweets in english language. When using this tools for portuguese comments, many tweets end up in the wrong classification. It happens since those tools are generally trained with algorithms modeled to parse and extract english words. In Brazil, there is a quite interesting web tool called Opsys developed by Thomas Lopes  which is focused on mining opinions from feeds and tweets in the web. Currently, its focus is on brazilian elections 2010 and investments (companies stocks). It works really well with portuguese texts and have a nice web summarization tool for analysis.

But since it is a new area, specially working with portuguese corpora I've decided to develop a simple working sentiment analysis tool for identifying opinions on from Twitter. For this, I apply a common and simple machine learning technique called Naive Bayes to classify the set of tweets related to movie reviews  which I will explain more about it in the next sections.


Ok, But how does the sentiment analysis work ?! What are the required steps ?
  1. Data Collection and Pre-processing:  In this step, it is important to search in the web the item of interest, that is, what you want to know the opinion about. It is important also to remove all facts that don't express opinions like news and objective phrases. if your system doesn't identify  subjectivity. The focus is on the user's opinions. The pre-processing is also important in order to remove unnecessary words or irrelevant words to the next step: The classification. 
      2. Classification: The polarity of the content that must be identified. Generally, the polarities used are positive, negative or neutral.

      3.  Presentation of Results: In this step, the classification of several opinions must be summarized in order to be presented to the user. The goal is to facilitate the understanding and give a general comprehension about what people are talking about an item.  This summarization can be expressed in graphics or text. 


Data Collection and Pre-processing

The first step (Data Collection) is related to the information retrieving. It is necessary to extract keywords from the text that may lead to correct classification. Keywords about the original data are usually stored in the form of a feature vector, F = (f1,f2,... fn).  Each coordinate of a feature vector represents one word, also called a feature, of the original text.  The value for each feature may be a binary value, indicating the presence or absence of the feature, an integer which may further express the intensity of the feature in the original text.  It is important to have a good selection of features since it strongly influences the subsequent learning in the machine learning process.  The goal of selecting good features is to capture the desired properties of the original text that are relevant for the sentiment analysis task. Unfortunately, this task for finding best features does not exist. It is required to rely on our intuition, the domain knowledge and a lot of experimentation to choose the best set of features. I strongly recommend the study of the  Natural Language Processing (NLP)  subject, which it may help you to understand this vast research field.

Our approach includes the use of Bag-of-Words. It is a popular model used in Information Retrieving that takes individual words (unigrams) in sentence as features, assuming their conditional independence. So the whole text is represented by a unordered collection of words.  Each feature in the vector represents a existence of one word. The challenge with this approach is the choice of words that are appropriate to become features.

For instance, considering this model, the tweet:  'Assisti hoje o filme Eclipse, ele é lindo !'  may be represented by the following feature vector:

 F = {'Assisti': 1 , 'hoje': 1, 'o': 1, 'filme': 1, 'Eclipse': 1, 'ele': 1, 'é': 1, 'lindo':1}

Here we represent the feature vector as a python dictionary.

Obviously, for any real use, we have to compare this vector to a feature vector that would have much larger number of words. It would be necessary in fact a dictionary of the language, however this model would be inefficient since it would overfit and lead to bad performance when exposed to new examples.
In literature, a common approach is to manually select the most important keywords, for example the word 'lindo' (adjective) is a good indicator of the author's opinion. The most important keywords such as 'excelente',  'horrível', 'fraco'  would be selected as features  since  they express polarity of a sentence). However, Pang et al. show that manual keyword model is outperformed by statistical models, where a good set of words that represent features are selected by their occurrence in the existent training corpus. So, the quality of the selection would depend on the size of the corpus and the similarity of domains of training and test data.  The use of corpus from different domains that don't have the same properties of the domain of the text we want to classify, may lead to inaccurate results. For instance, if the analysis is done on a set of tweets related to a product and is trained with a set based on movies, the most of the sentences would be misclassified.  It is important also to create a dictionary which will capture the most important features for classifying previously unseen sentences.

Additionally, it is possible to remove some of the existing words that bring little useful information like pronouns, articles, prepositions, etc (List of stop words).  Of course, the model presented here is simple, and there are several limitations, which include the inability to capture the polarity relation between words and different meanings of one word.  Another limitations would be suppressed by use of regular expressions for handling the negation and parts of speech for a syntax analysis of the word.

Classification

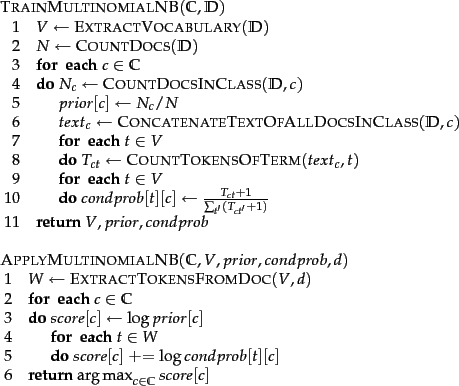
Classification algorithms are efficient and consolidated techniques for this sentiment classification task, since it predicts the label for a given input. However, depending on which approach used (supervised or unsupervised), it will be required a training set with labeled examples before new tweets be classified. It is important to train the model with the set in a domain related to the data domain that will be used as input. The labels we are interested here are the subjectivity of the sentence and the polarity of the sentence (neutral, positive or negative).  There are several machine learning techniques for this task, but in this article we are using the simplest one but with a great  efficience in classification problems: Naive Bayes technique.

The Naive Bayes model or Naive Bayer classifier is a simple probabilistic classifier based on the Baye's theorem with strong independence assumptions. In simple terms, this probability model assumes that the presence or absence of a particular feature of a class is unrelated to presence or absence of any other feature.  For instance, a car may be considered to be a vehicle if there are  4 tires, engine and at least 2 doors.  Even if these features depend on each other, the naive Bayes classifier considers all these properties to independently contribute to the probability that the car is an vehicle.

In our case, each stemmed word in a tweet is taken to be a unique variable in the model, and the goal is to find the probability of that word, and consequently the all sentence itself, belonging to a certain class: Positive vs Negative.  In spite of their naive design and simplified assumptions,  naive Bayes classifiers have worked very well in many complex real-word situations. One of the extensive uses is in spam filtering. In fact, one of the most popular packages (SpamAssassin) is a direct implementation of Naive Bayes. It is a an amazingly simple approach and also a powerful classifier.  More information about the algorithm of Naive Bayes it can be found here and here.
In this tutorial I have used the implementation of a simple Naive Bayesian Classifier. There are some variations using Fisher Score discriminant function, which will not be explored in this article now.
In our problem domain, we will use the Naive Bayes classifier to classify the tweets in Positive or Negative.  To apply this task, it is necessary to train the classifier by creating a training set of tweets (or words) already classified (in Positive or  Negative). Trained the model,  Naive Bayes assumes that all features in the feature vector (after the pre-processing step), and applies Bayes' rule on the tweet. Naive Bayes calculates the prior probability frequency for each label in the training set. Each label is given a likelihood estimate from the contributions of all features, and the sentence is assigned the label with highest likelihood estimate, that is, 'Positive' or 'Negative'. 


Summarization

The last step: The presentation of the results. Generally, it can be presented by using text or charts. The summarization in text is not a easy task, and it has a research field only for it. The common presentation is a list of sentences where for each the classification is shown by its side.

Summarization by TwitterSentiment Analyzer  -  http://twittersentiment.appspot.com/


The other common option is to use charts to present the results. It's the simplest way, and there are many flavors for this presentation. And don't forget they are more attractive for the end users and reports.


Summarization by TwitterSentiment Analyzer  -  http://twittersentiment.appspot.com/


Our Study Case:  Movies Reviews on Twitter

For a simple study case and demonstration here, I've created a training set with more about 300 sentences related to movie reviews on Twitter. So sentences such as 'Eu amei o filme Eclipse!' or 'Eclipse poderia ser melhor. #horrível Pior filme da saga.'  are  labeled under positive and negative polarities for creating the training set. It is important to notice that my data corpus are related to portuguese tweets.  So english ones will not work properly.  I've used the Twitter Search API for searching tweets with the keyword 'Eclipse',  the new released  movie in the theaters from the saga  'Twilight' and fetched tweets during three days (July 05th 2010 - July 07th 2010). 
What people are talking about the movie Eclipse on Twitter ??
The task is to analyze the opinions about the movie in Twitter. Using the Naive Bayes Classifier with some adjustments to include the 'Neutral' Classification, we have analyzed 4265 tweets.  I have used some pre-processing techniques explained above. All the code was written in Python. The result you can see in the graph below.

Polarity Chart on tweets about the movie 'Eclipse'

As you may notice, brazilians are really loving the movie Eclipse!! There are also a great amount on neutral tweets, it means that the classifier didn't have the confidence to classify as positive or negative, (I'll explain soon) or tweets that don't express sentiment (opinions).

You can see some of the tweets classified as follows:

Some Tweets classified related to the movie Eclipse

The neutral classification, I've added a simple threshold where after evaluating the probabilities for each polarity (Positive and Negative). The maximum one is compared to a threshold and if its value isn't higher, it is classified as a neutral one. It means that the classifier doesn't have the confidence to classify the tweet as one of the classes trained in the model.

As you can see, the Naive Bayes is a simple machine learning technique quite efficient for automatically extract sentiment from small sentences like Tweets. However, it is important to notice that it still can be improved with new feature extraction approaches or another robust machine learning techniques.

Demo

Soon I will provide all the source code for this project, but if you want to play around with the classifier, I've developed a simple REST API for using the classifier for simple tests. This version is still not official and it only works with movie reviews domain (in portuguese of course).

Docummentation 

The output result is in JSON. PLEASE THIS API is still in development. So if you plan on integrating this API into a product, please let me know , so that I can contact you in order to help you to create your own.

The classifier is only working with a single arbitrary text (in portuguese language)  and as result give you its polarity. Example:
Query:
http://mobnip.appspot.com/api/sentiment/classify?text=Encontro+Explosivo+filme+ruim+Danado&query=encontro+explosivo

Response:

{"results": {"polarity": "negativo", "text": "Encontro Explosivo filme ruim Danado", "query": "encontro explosivo"}}


Parameters:
- text: The text you want to classify. This should be URL encoded. 
- query: The subject. This should be URL encoded. (optional)
Response:
- text: original text submitted
- query: original query submitted
- polarity. The polarity values are:
       -  'negativo': corresponds to negative
       -  'neutro': corresponds to neutral
       - 'positivo': corresponds to positive


Conclusions

As we can notice that sentiment analysis is a trend in the Web, with several interesting application with a lot of data sources provided by users.  Microblogs and Social Networks such as Twitter, Facebook and Orkut and another web services are powerful crowding sources for obtain opinions from the users in the Web about any subject and specially to help to answer the question about what people are interested on. Despite the challenge, more companies and researchers are working in this area until one day it would be easy for users and companies to simply obtain complete and rich summarized reports about the opinions from the Web in order to support them in the decision making process in their daily life.

 In machine learning topics, there are also a lot of improvements that would be made for this task and several challenges for researchers to extend it. I would say the most important ones are related to the natural language processing, which is directly associated to sentiment analysis. I would cite the subjectivity identification (distinguish if a text is really a opinion or a fact), identification  of sarcasms, which are not easy to extract,  the multiple reference of items in a same sentence (a tweet referencing Iphone and Ipod) and with different opinions, which it may confuse the classification. Misspelling words and abbreviated words (common in blogs and social networks) are also difficulties for search and classification. Many others could be cited here but it may be found if you search on Google about sentiment analysis.

In the end, I would tell that applying sentiment analysis in portuguese language is still a new area with great challenges to deal with text mining since the language is different from the current ones applied on english in the literature. My work is  a initial discussion about how we can learn more about sentiment analysis and how portuguese could be inserted in this context.  More analysis and a better evaluation should be applied to compare another popular machine learning techniques with Naive Bayes classifier.

I expect   you have enjoyed this tutorial, it's quite long but I believe it could be a useful start for the beginners in machine learning.

Thanks,

See you next time!

Marcel Caraciolo